Taalas Flagship - ChatJimmy - The 14,000 T/s Very Capable and Near Instant LLM
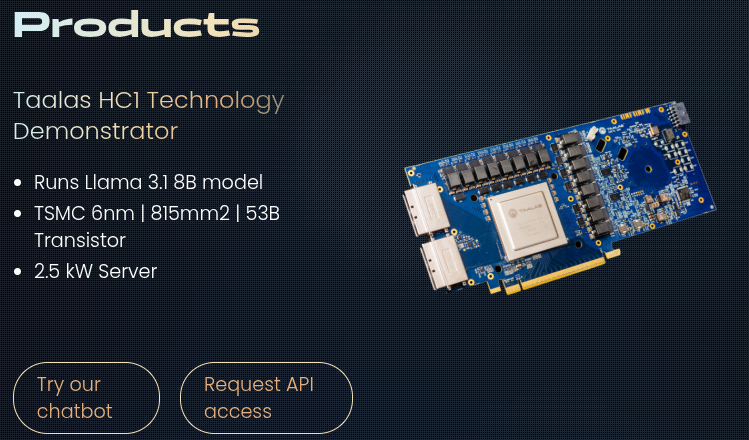
We look at one of the worlds fastest basic LLM inference tools - ChatJimmy at 14,000 T/s
chat jimmy
chat jimmy LLM web interface
It's so fast it's ridiculous, and that's just what is so beautiful about Taalaas based demonstrator - ChatJimmy. No it doesn't do long contexts, or any of that stuff, it barely keeps a session cookie. It's severely limited a session to 6144 Tokens.
But it's really - really REALLY fast. Like so fast you won't see it even update.
Bias Against the 8B
- There is a ongoing bias against 8B sized models, simply in that an 8B from a year ago were not as tuned, not as good, and not as capable as an 8B today. So people feel they need a giant montrosity of a 2.8T sized model or what have you - but you will quickly see that you can rock out some pretty good obscure work. When we asked it some Goertzel based coding questions - that's pretty obscure, and it nailed out out of the park, even going so far as to do it in cuda code.
Enough - here is some of it's output, done faster than you can blink
Give me a Goertzel ExampleThe output:
   """
    coefficients = goertzel(x0, y0)
    return np.polyval(coefficients, x)

# Example usage
# Fit a cubic polynomial to some data
x0 = np.array([1, 2, 3, 4, 5])
y0 = np.array([2, 3, 5, 6, 8])
x = 4

# Calculate the coefficients
coefficients = goertzel(x0, y0)

# Print the coefficients
print("Coefficients: ", coefficients)

# Calculate the polynomial value at x
result = goertzel_polynomial(x, 4, x0, y0)

# Print the result
print("Polynomial value at x=4: ", result)
show me in C
Again it produced output so ridiculously fast you hardly noticed it go.
#include <iostream>
#include <cmath>
#include <vector>

// Function to calculate the polynomial value at a given point
double goertzel_polynomial(double x, double x0, double* coefficients, int degree) {
    double result = 0.0;
    for (int i = 0; i <= degree; i++) {
        result += coefficients[i] * pow(x, i);
    }
    return result;
}

// Function to fit a polynomial using the Goertzel algorithm
void goertzel_coefficients(double* x, double* y, int n, int degree, double* coefficients) {
    // Create matrix A for the system of equations
    int m = degree + 1;
    double A[m * (n+1);
    for (int i = 0; i < m; i++) {
        double sum = 0.0;
        for (int j = 0; j < n; j++) {
            sum += pow(x[j], i);
        }
        for (int j = 0; j <= i; j++) {
            A[i * (n+1) + j] = sum;
        }
    }

    // Solve the system of equations using the least squares method
    int m2 = m * (n+1);
    double B[m2];
    for (int i = 0; i < m2; i++) {
        double sum = 0.0;
        for (int j = 0; j < n; j++) {
            sum += x[j] * B[j * m + i];
        }
        B[i] = sum;
    }

    for (int i = 0; i < m2; i++) {
        for (int j = 0; j < m2; j++) {
            if (i == j) {
                B[i] = 1.0;
            } else {
                B[i] -= A[i * (n+1) + j];
            }
        }
    }

    // Solve the system of equations
    double L = 0.0;
    for (int i = 0; i < m2; i++) {
        L = L + pow(B[i], 2);
    }
    L = 1 / L;

    for (int i = 0; i < m2; i++) {
        B[i] *= L;
    }

    // Back substitute to find the coefficients
    for (int i = m-1; i >= 0; i--) {
        for (int j = i+1; j < m2; j++) {
            B[j * (n+1) + i] -= B[j] * A[j * (n+1) + i];
        }
        L = 0.0;
        for (int j = i+1; j < m2; j++) {
            L += B[j * (n+1) + i] * A[i * (n+1) + j];
        }
        L = B[i] / L;
        B[i] = 0.0;
        for (int j = i+1; j < m2; j++) {
            B[j * (n+1) + i] = (L * B[j]);
        }
    }

    // Store the coefficients
    for (int i = 0; i <= degree; i++) {
        coefficients[i] = B[i * (n+1)];
    }
}

int main() {
    int degree = 3;
    int n = 5;
    double x[] = {1, 2, 3, 4, 5};
    double y[] = {2, 3, 5, 6, 8};
    double coefficients[4];

    goertzel_coefficients(x, y, n, degree, coefficients);

    double x0 = 4;
    double result = goertzel_polynomial(x0, x, y, degree, coefficients);

    std::cout << "Coefficients: ";
    for (int i = 0; i <= degree; i++) {
        std::cout << coefficients[i] << " ";
    }
    std::cout << std::endl;

    std::cout << "Polynomial value at x=4: " << result << std::endl;

    return 0;
}
Next we tried something a little more obscure, and asked it to code it in Cuda: Give me a Goertzel Example in Cuda
- Again blink - it's done.
// Goertzel algorithm implementation in CUDA
// Compile with: nvcc -o goertzel_kernel.o -c goertzel_kernel.c
// Run with: time ./goertzel

#include <cuda_runtime.h>
#include <stdio.h>
#include <math.h>

// Function to calculate the polynomial value at a given point
__global__ void goertzel_polynomial(float* x, float* y, int n, int degree, float* result) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    int idx0 = blockIdx.y * blockDim.y + threadIdx.y;
    if (idx < n) {
        float x0 = x[idx];
        float sum = 0.0f;
        for (int i = 0; i <= degree; i++) {
            sum += powf(x0, i);
        }
        result[idx] = sum;
    }
}

// Function to fit a polynomial using the Goertzel algorithm
__global__ void goertzel_coefficients(float* x, float* y, int n, int degree, float* coefficients) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < degree + 1) {
        float sum = 0.0f;
        for (int i = 0; i < n; i++) {
            sum += x[i];
        }
        coefficients[idx] = sum;

        for (int i = 0; i < degree; i++) {
            sum = 0.0f;
            for (int j = 0; j < n; j++) {
                sum += powf(x[j], i+1);
            }
            coefficients[i+1] = sum;
        }
    }
}

// Kernel function to calculate the coefficients
__global__ void calculate_coefficients(float* x, float* y, int n, int degree, float* coefficients) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < degree + 1) {
        int m = degree + 1;
        float sum = 0.0f;
        for (int i = 0; i < n; i++) {
            sum += y[i] * coefficients[i];
        }
        coefficients[m * idx] = sum;
        sum = 0.0f;
        for (int i = 0; i < n; i++) {
            sum += powf(x[i], m * idx);
        }
        coefficients[m * (idx + 1] = sum;
    }
}

// Function to calculate the polynomial value at a given point
int goertzel_polynomial(float x, float x0, float* coefficients, int degree) {
    int m = degree + 1;
    float sum = 0.0f;
    for (int i = 0; i < m; i++) {
        sum += coefficients[i] * powf(x0, i);
    }
    return sum;
}

int main() {
    int degree = 3;
    int n = 5;
    float x[] = {1, 2, 3, 4, 5};
    float y[] = {2, 3, 5, 6, 8};
    float coefficients[4];
    float result;

    // Allocate memory on the device
    int blockSize = 1;
    int numBlocks = (degree + 1 + n - 1) / blockSize;
    int numThreads = n;
    float* x_d;
    float* y_d;
    float* coefficients_d;
    float* result_d;

    cudaMalloc((void**)&x_d, n * sizeof(float));
    cudaMalloc((void**)&y_d, n * sizeof(float));
    cudaMalloc((void**)&coefficients_d, (degree + 1) * sizeof(float));
    cudaMalloc((void**)&result_d, sizeof(float));

    // Copy data to the device
    cudaMemcpyAsync(x_d, x, n * sizeof(float), cudaMemcpyHostToDevice);
    cudaMemcpyAsync(y_d, y, n * sizeof(float), cudaMemcpyHostToDevice);

    // Launch the kernel
    dim3 block(1, 1);
    dim3 grid((degree + 1 + n - 1) / blockSize, 1);
    calculate_coefficients<<<grid, block>>>(x, y, n, degree, coefficients_d);

    // Synchronize the device
    cudaDeviceSynchronize();

    // Copy data back to the host
    cudaMemcpy(&coefficients, coefficients_d, (degree + 1) * sizeof(float), cudaMemcpyDeviceToHost);

    // Launch the kernel again to calculate the result
    dim3 block1(1, 1);
    dim3 grid1(1, 1);
    goertzel_polynomial<<<grid1, block1>>>(x_d, coefficients_d, degree, x, &result_d);

    // Synchronize the device
    cudaDeviceSynchronize();

    // Copy data back to the host
    cudaMemcpy(&result, result_d, sizeof(float), cudaMemcpyDeviceToHost);

    // Print the coefficients and the result
    printf("Coefficients: ");
    for (int i = 0; i <= degree; i++) {
        printf("%f ", coefficients[i]);
    }
    printf("\n");
    printf("Polynomial value at x=4: %f\n", result);

    // Free the device memory
    cudaFree(x_d);
    cudaFree(y_d);
    cudaFree(coefficients_d);
    cudaFree(result_d);

    return 0;
}
Conclusion
- We don't need to spend a lot of time on this thing for anyone realize it's a incredibly fast LLM for quick one-offs in very small-contexts.
- If you need very fast code blocks, very fast summaries, and don't mind the small context windows this thing is gold!